NVIDIA said its newest racks make AI answers up to 10x cheaper.
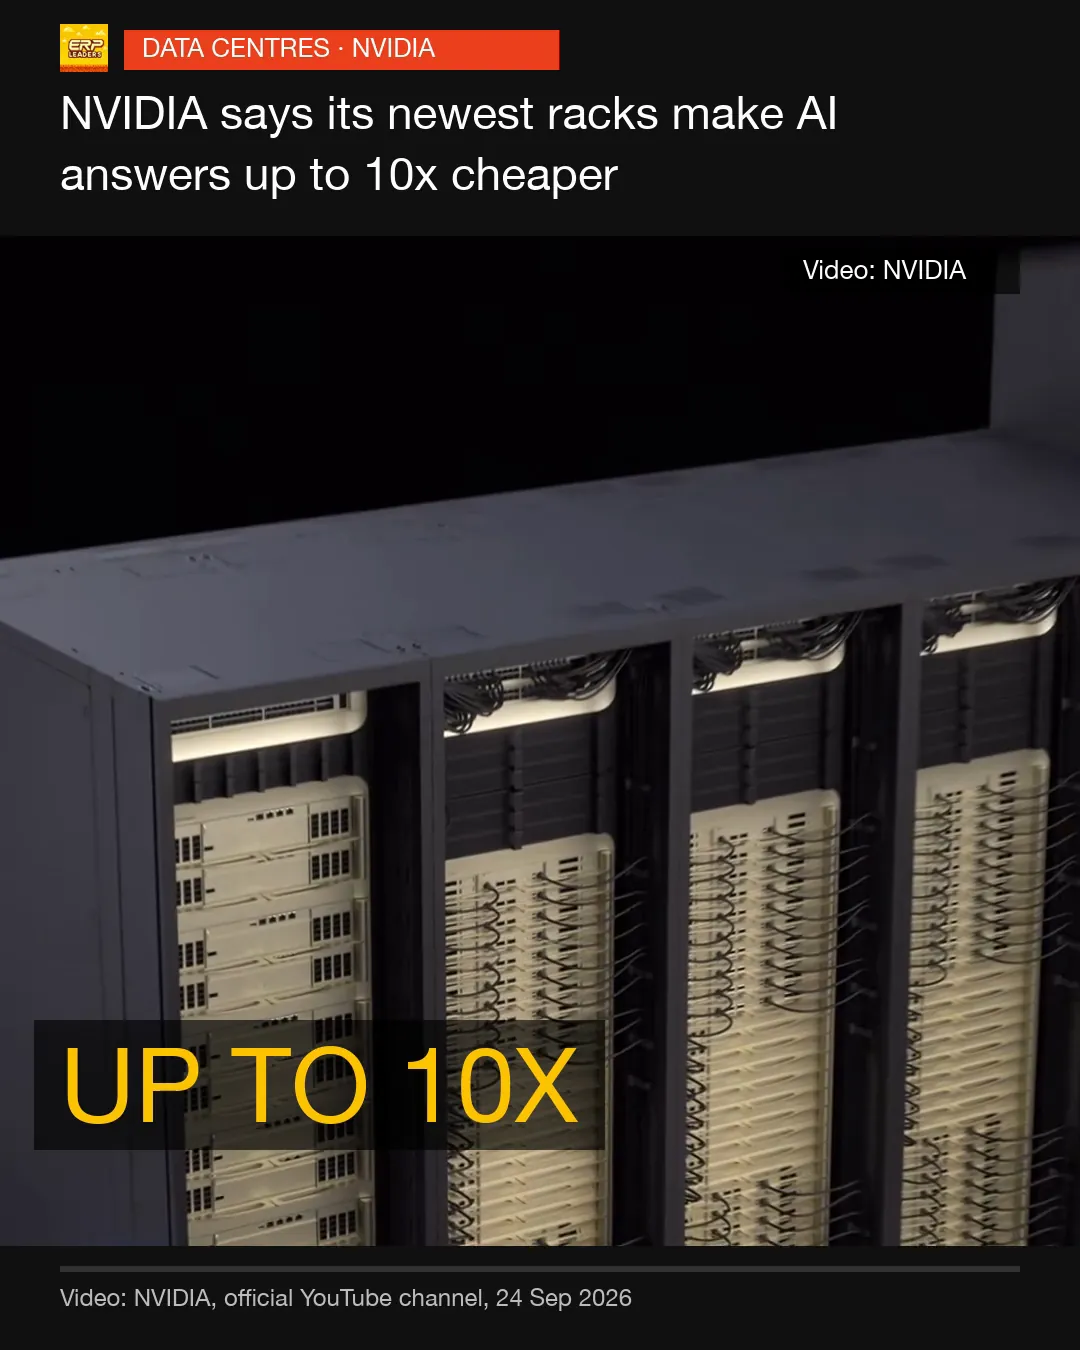
The claim comes from a film NVIDIA posted on 24 September for ten years of DGX, its line of AI computers. NVIDIA says its Vera Rubin rack-scale system shows "up to a 10x reduction in inference token costs". That is the cost of each piece of text a model writes when it answers. The film does not say which older system provided the baseline or identify the model and workload behind the 10x.
CEO Jensen Huang hand-delivered the first DGX-1 to OpenAI in 2016, NVIDIA says. In 2017, it says, Meta's AI research lab trained on the ImageNet picture dataset in an hour using the DGX-1.
NVIDIA says BNY was the first major bank to deploy a DGX SuperPOD, a cluster of DGX systems, with NVIDIA Hopper chips. It says DeepL cut the time to translate the entire web by 90%, and that DGX runs AI agents in Foxconn's factories.
The 10x is a cost per token. The film does not say whether power, networking, software or how busy the racks are went into that figure, and each of them shows up on an AI bill.
The rack shots at the start and end of our report are NVIDIA's product renders.
🎥 Video: NVIDIA, official YouTube channel · narration: AI voice
What the captions say
- NVIDIA says these racks cut AI costs up to 10x.
- It all began with one box.
- In 2016 NVIDIA hand-delivered it to OpenAI.
- In 2017, Meta's lab broke training records.
- BNY was the first big bank to install a cluster.
- Foxconn runs factory AI agents on it.
- Up to 10x cheaper than what? The film does not say.